 R package rEMM - Extensible Markov Model for Modelling Temporal
Relationships Between Clusters
The hardware and bandwidth for this mirror is donated by dogado GmbH, the Webhosting and Full Service-Cloud Provider. Check out our Wordpress Tutorial.
If you wish to report a bug, or if you are interested in having us mirror your free-software or open-source project, please feel free to contact us at mirror[@]dogado.de.
R package rEMM - Extensible Markov Model for Modelling Temporal
Relationships Between Clusters

Maintainer: Michael Hahsler
Implements TRACDS (Temporal Relationships between Clusters for Data Streams), a generalization of the Extensible Markov Model (EMM), to model transition probabilities in sequence data (Hahsler and Dunham 2011). TRACDS adds a temporal or order model to data stream clustering by superimposing a dynamically adapting Markov chain. It also provides an implementation of EMM (TRACDS on top of tNN data stream clustering) (Hahsler and Dunham 2010).
The package also provides interface classes DSC_tNN and DSC_EMM for
data stream mining with stream
(Hahsler et al. 2017).
Stable CRAN version: Install from within R with
install.packages("rEMM")Current development version: Install from r-universe.
install.packages("rEMM",
    repos = c("https://mhahsler.r-universe.dev",
"https://cloud.r-project.org/"))We use an artificial dataset with four clusters. Points are generated using the fixed sequence <1,2,1,3,4> through the four clusters. The lines below indicate the sequence.
library(rEMM)

data("EMMsim")

plot(EMMsim_train, pch = NA)
lines(EMMsim_train, col = "gray")
points(EMMsim_train, pch = EMMsim_sequence_train)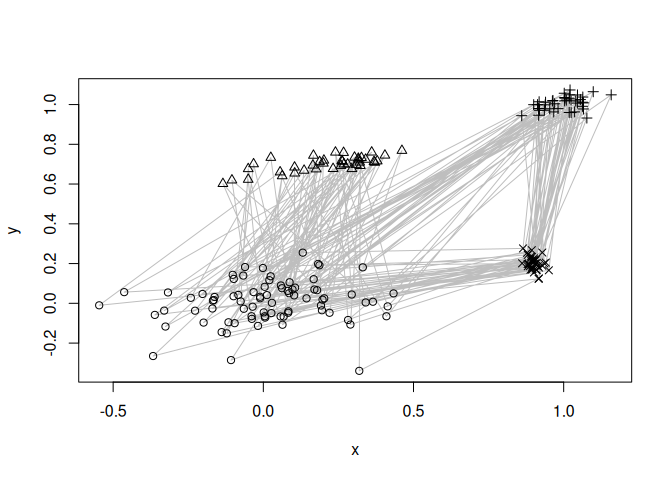
EMM recovers the components and sequence information. We use EMM and then recluster the learned structure, assuming that we know there are four components. The graph below represents a Markov model of the sequence.
emm <- EMM(threshold = 0.1, measure = "euclidean")
build(emm, EMMsim_train)
emmc <- recluster_hclust(emm, k = 4, method = "average")
plot(emmc, method = "MDS")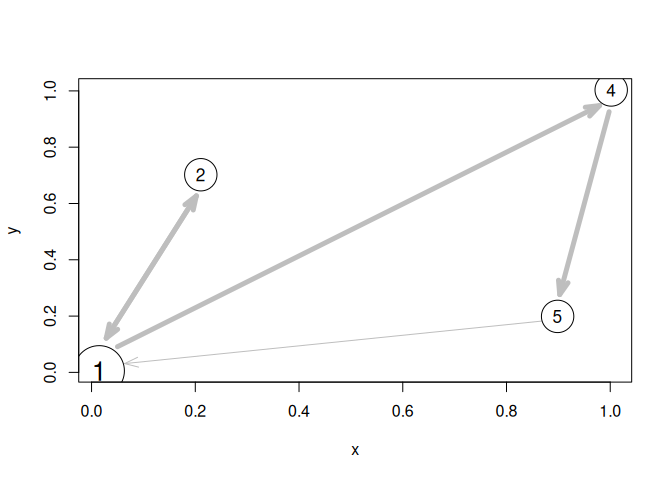
We can now score new sequences. Here, we use a test sequence created in the same way as the training data and calculate the product of the transition probabilities in the model. A high score indicates a good match.
score(emmc, EMMsim_test)## [1] 0.71Development of this package was supported in part by NSF IIS-0948893 and R21HG005912 from the National Human Genome Research Institute.
These binaries (installable software) and packages are in development.
They may not be fully stable and should be used with caution. We make no claims about them.
Health stats visible at Monitor.